💡 Quick Answer: Deep learning is a type of machine learning that uses layered structures called neural networks to learn patterns automatically from raw data like pixels in a photo or sound waves in audio instead of a person manually deciding which features matter. It’s called “deep” because these networks stack many layers on top of each other, each one refining what the previous layer detected. Face unlock, real-time translation apps, voice assistants, and AI chatbots are all everyday examples of deep learning at work.
If you’ve read ReviewNPrep’s guides on what AI is and what machine learning is, you already know deep learning is a more advanced type of machine learning. This guide goes further into exactly what makes it different, how a neural network actually works underneath, and why deep learning powers most of the AI that feels impressively capable today from face unlock to real-time translation.
Despite the technical-sounding name, the underlying idea is easier to picture than most explanations make it sound.
What Deep Learning Actually Means, in Plain English
Regular machine learning often needs help from a person. To teach a model to recognize spam email, someone typically has to decide in advance which features matter, word frequency, sender reputation, number of links and feed those specific features to the model.
Deep learning skips that step. Instead of a person deciding what matters, you feed the raw data straight in the actual pixels of an image, or the raw waveform of an audio clip and the network figures out on its own which patterns are useful, layer by layer, without anyone telling it what to look for.
That’s the core difference: traditional machine learning usually needs help deciding what to pay attention to. Deep learning learns what to pay attention to by itself, given enough examples.
What Is a Neural Network?
A neural network is a structure made of layers of simple, connected units loosely inspired by how neurons connect in the brain, though the comparison shouldn’t be taken too literally. Each layer takes the output of the layer before it, transforms it slightly, and passes it forward.
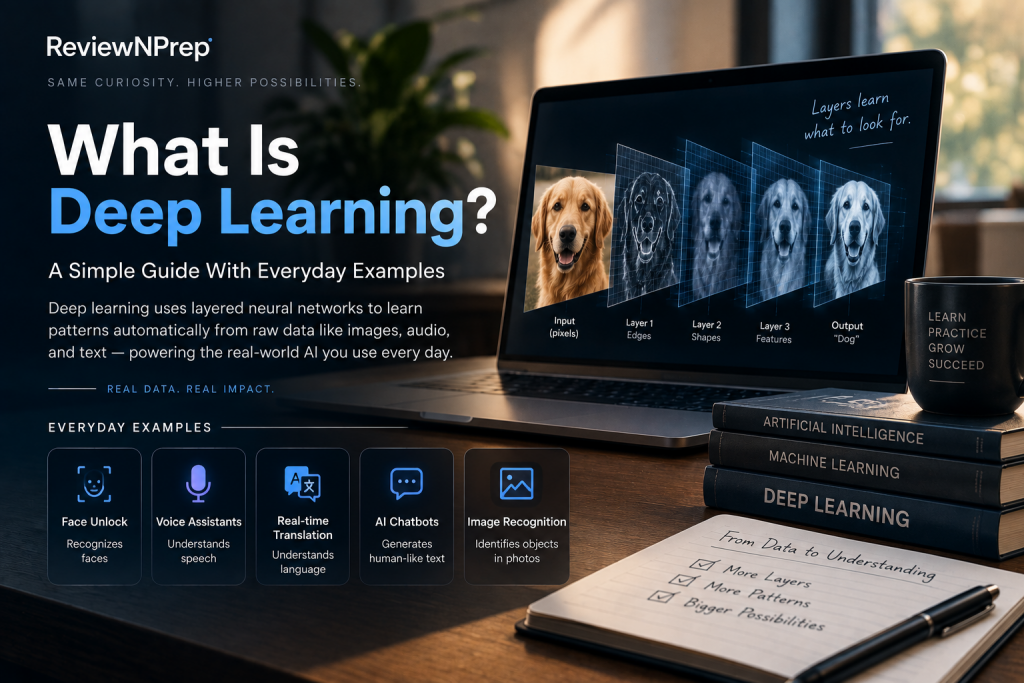
Picture recognizing a photo of a face, layer by layer:
- The first layer might detect simple edges and contrast where light meets dark in the image.
- The next layer combines those edges into basic shapes, curves, circles, lines.
- A deeper layer combines those shapes into recognizable features: an eye, a nose, a mouth.
- The final layer combines all of that into a decision: “this is a face,” or even “this is a specific person’s face.”
Nobody programmed the network to look for edges first and faces last; it discovered that hierarchy on its own by seeing enough labeled examples during training. That automatic discovery of useful features, layer by layer, is the single biggest reason deep learning became so powerful for images, audio, and language.
Why “Deep”? Shallow vs. Deep Networks
A neural network with just one or two layers is sometimes called “shallow,” and it can still learn simple patterns. “Deep” learning refers to networks stacking many layers, sometimes dozens or even hundreds on top of each other.
More layers generally mean the network can build more abstract, more refined representations of the data before making a final decision. That extra depth is what allows deep learning to handle far more complex problems recognizing thousands of object categories, understanding natural spoken language, generating coherent text than shallow networks or traditional machine learning typically can.
AI vs. Machine Learning vs. Deep Learning, Revisited
| Term | Who Decides What Features Matter | Everyday Example |
| Traditional Machine Learning | Often a person, based on domain knowledge | A fraud model using pre-selected features like transaction amount and location |
| Deep Learning | The network itself, learned automatically from raw data | Face unlock learning facial features directly from pixel data |
How Deep Learning Actually Learns
Think of a dart player learning to hit a bullseye blindfolded, with someone telling them only how far off each throw landed. Over many throws, they gradually adjust their aim based on that feedback until their throws land closer and closer to the center.
A neural network learns the same way, in four repeating steps:
- Forward pass the network makes a prediction based on its current (initially random) internal settings.
- Measure the error the prediction is compared against the correct answer, producing a number representing how wrong it was.
- Backpropagation the network works backward through its layers, figuring out which internal settings contributed most to the error.
- Adjust and repeat those settings are nudged slightly to reduce the error, and the whole process repeats, often millions of times, across huge amounts of training data.
Each individual adjustment is tiny. It’s the sheer number of repetitions, across enormous datasets, that gradually turns a network of random guesses into one that recognizes faces, transcribes speech, or writes coherent sentences.
Everyday Examples of Deep Learning You Already Use
- Face unlock smartphones use deep learning to recognize facial features from a camera image.
- Real-time translation apps convert spoken or written language by learning patterns across huge multilingual datasets.
- Voice assistants understand natural, conversational speech rather than a fixed set of commands.
- Medical image analysis tools that help flag potential issues in X-rays or scans by learning from large sets of labeled medical images.
- Self-driving car perception object detection systems that identify pedestrians, vehicles, and signs from camera and sensor data.
- AI chatbots generate human-like text by learning patterns across massive amounts of written language.
Why Deep Learning Needs So Much Data and Computing Power
A deep neural network can have millions or even billions of internal settings that need tuning. Tuning that many settings reliably requires seeing a very large number of examples; a dataset of a few hundred items usually isn’t enough for a deep network to learn meaningful patterns, even though it might be plenty for a simpler model.
That scale is also why deep learning relies heavily on specialized computing hardware (GPUs) capable of performing huge numbers of calculations in parallel. This is part of why deep learning only became widely practical once large datasets and powerful hardware became affordable and available. The core mathematical ideas behind neural networks are decades older than their recent popularity suggests.
Common Deep Learning Misconceptions
- Misconception: Deep learning “understands” what it processes.
A network that generates fluent, human-like text or accurately labels an image is still recognizing statistical patterns; it has no awareness of meaning behind the words or objects it identifies. - Misconception: Deep learning is always the better choice.
For smaller datasets or simpler, well-structured problems, traditional machine learning often performs just as well, trains far faster, and is easier to explain. Deep learning’s advantage shows up specifically on large, complex, unstructured data like images and language. - Misconception: A deep learning model can always explain its own decision.
Deep networks are frequently described as “black boxes” because their internal reasoning spread across millions of tuned settings is difficult for even their own creators to fully interpret, which matters in regulated fields like healthcare and finance. - Misconception: Deep learning is only relevant to major tech companies.
Deep learning tools now appear in healthcare diagnostics, retail demand forecasting, agriculture, and manufacturing quality inspection well beyond the handful of companies that pioneered the technique.
Why Deep Learning Basics Matter for Your Career
Understanding deep learning at a conceptual level is increasingly relevant even outside engineering roles; it helps you evaluate whether a vendor’s “AI-powered” claim is grounded in something real, and where a deep learning system is likely to be reliable versus where it’s likely to fail.
If you’re building toward a hands-on role, AWS Certified Machine Learning Engineer – Associate (covered in ReviewNPrep’s AWS Certification Roadmap) includes deep learning fundamentals as part of its content outline, and the newer Generative AI Developer – Professional path builds directly on these concepts for candidates working with large language models.
FAQs
1) What is deep learning in simple terms?
Deep learning is a type of machine learning that uses layered structures called neural networks to learn patterns automatically from raw data like pixels in an image or sound waves in audio instead of a person manually deciding which features matter.
2) What’s the difference between machine learning and deep learning?
Deep learning is a subset of machine learning. Traditional machine learning often needs a person to hand-pick which features of the data matter, while deep learning uses multiple layers in a neural network to discover useful features automatically, directly from raw data.
3) What is a neural network?
A neural network is a structure made of layered nodes loosely inspired by neurons in the brain where each layer transforms the data a little further, passing it to the next layer until the final layer produces an output, like “this is a photo of a dog.”
4) Why does deep learning need so much data?
Deep neural networks have millions or billions of internal settings, called parameters, that need to be tuned. Tuning that many parameters accurately requires seeing a very large number of examples; a small dataset generally isn’t enough for the network to learn reliable patterns.
5) Is deep learning always better than traditional machine learning?
No. For smaller datasets or simpler problems, traditional machine learning methods often perform just as well, train much faster, and are easier to explain. Deep learning tends to pull ahead specifically on large, complex datasets like images, audio, and natural language.
6) What are some everyday examples of deep learning?
Face unlocking on smartphones, real-time language translation apps, voice assistants understanding natural speech, medical image analysis, self-driving car object detection, and AI chatbots that generate human-like text are all built on deep learning.
7) Do I need a math or programming background to understand deep learning basics?
Not to understand the core concepts. You can grasp what deep learning is, how it’s different from traditional machine learning, and where it’s used without writing code, building the models yourself is where math and programming become necessary.
Ready to Build on These Concepts?
Whether you’re starting with AI Practitioner or working toward Machine Learning Engineer – Associate, put your understanding to the test with ReviewNPrep’s free practice exams and flashcards.

Have questions or want to help the community? Share here.
We encourage our readers to share their unique experiences or ask questions to create a helpful and informative community. Our editors will also review every comment before publishing, ensuring our commitment to this community.